gro-light
a medium for publishing scientific work as it is made. in a collaborative graph rather than piles of pdfs.
here’s an example graph of some papers on hepatitis c. it looks messy, but it’s incredibly easy for a machine to tell you which contributions were key. and even at a glance, you can see which datasets (green squares) and methods (orange diamonds) were key, and which claims (blue hexagons and circles) were central (literally).
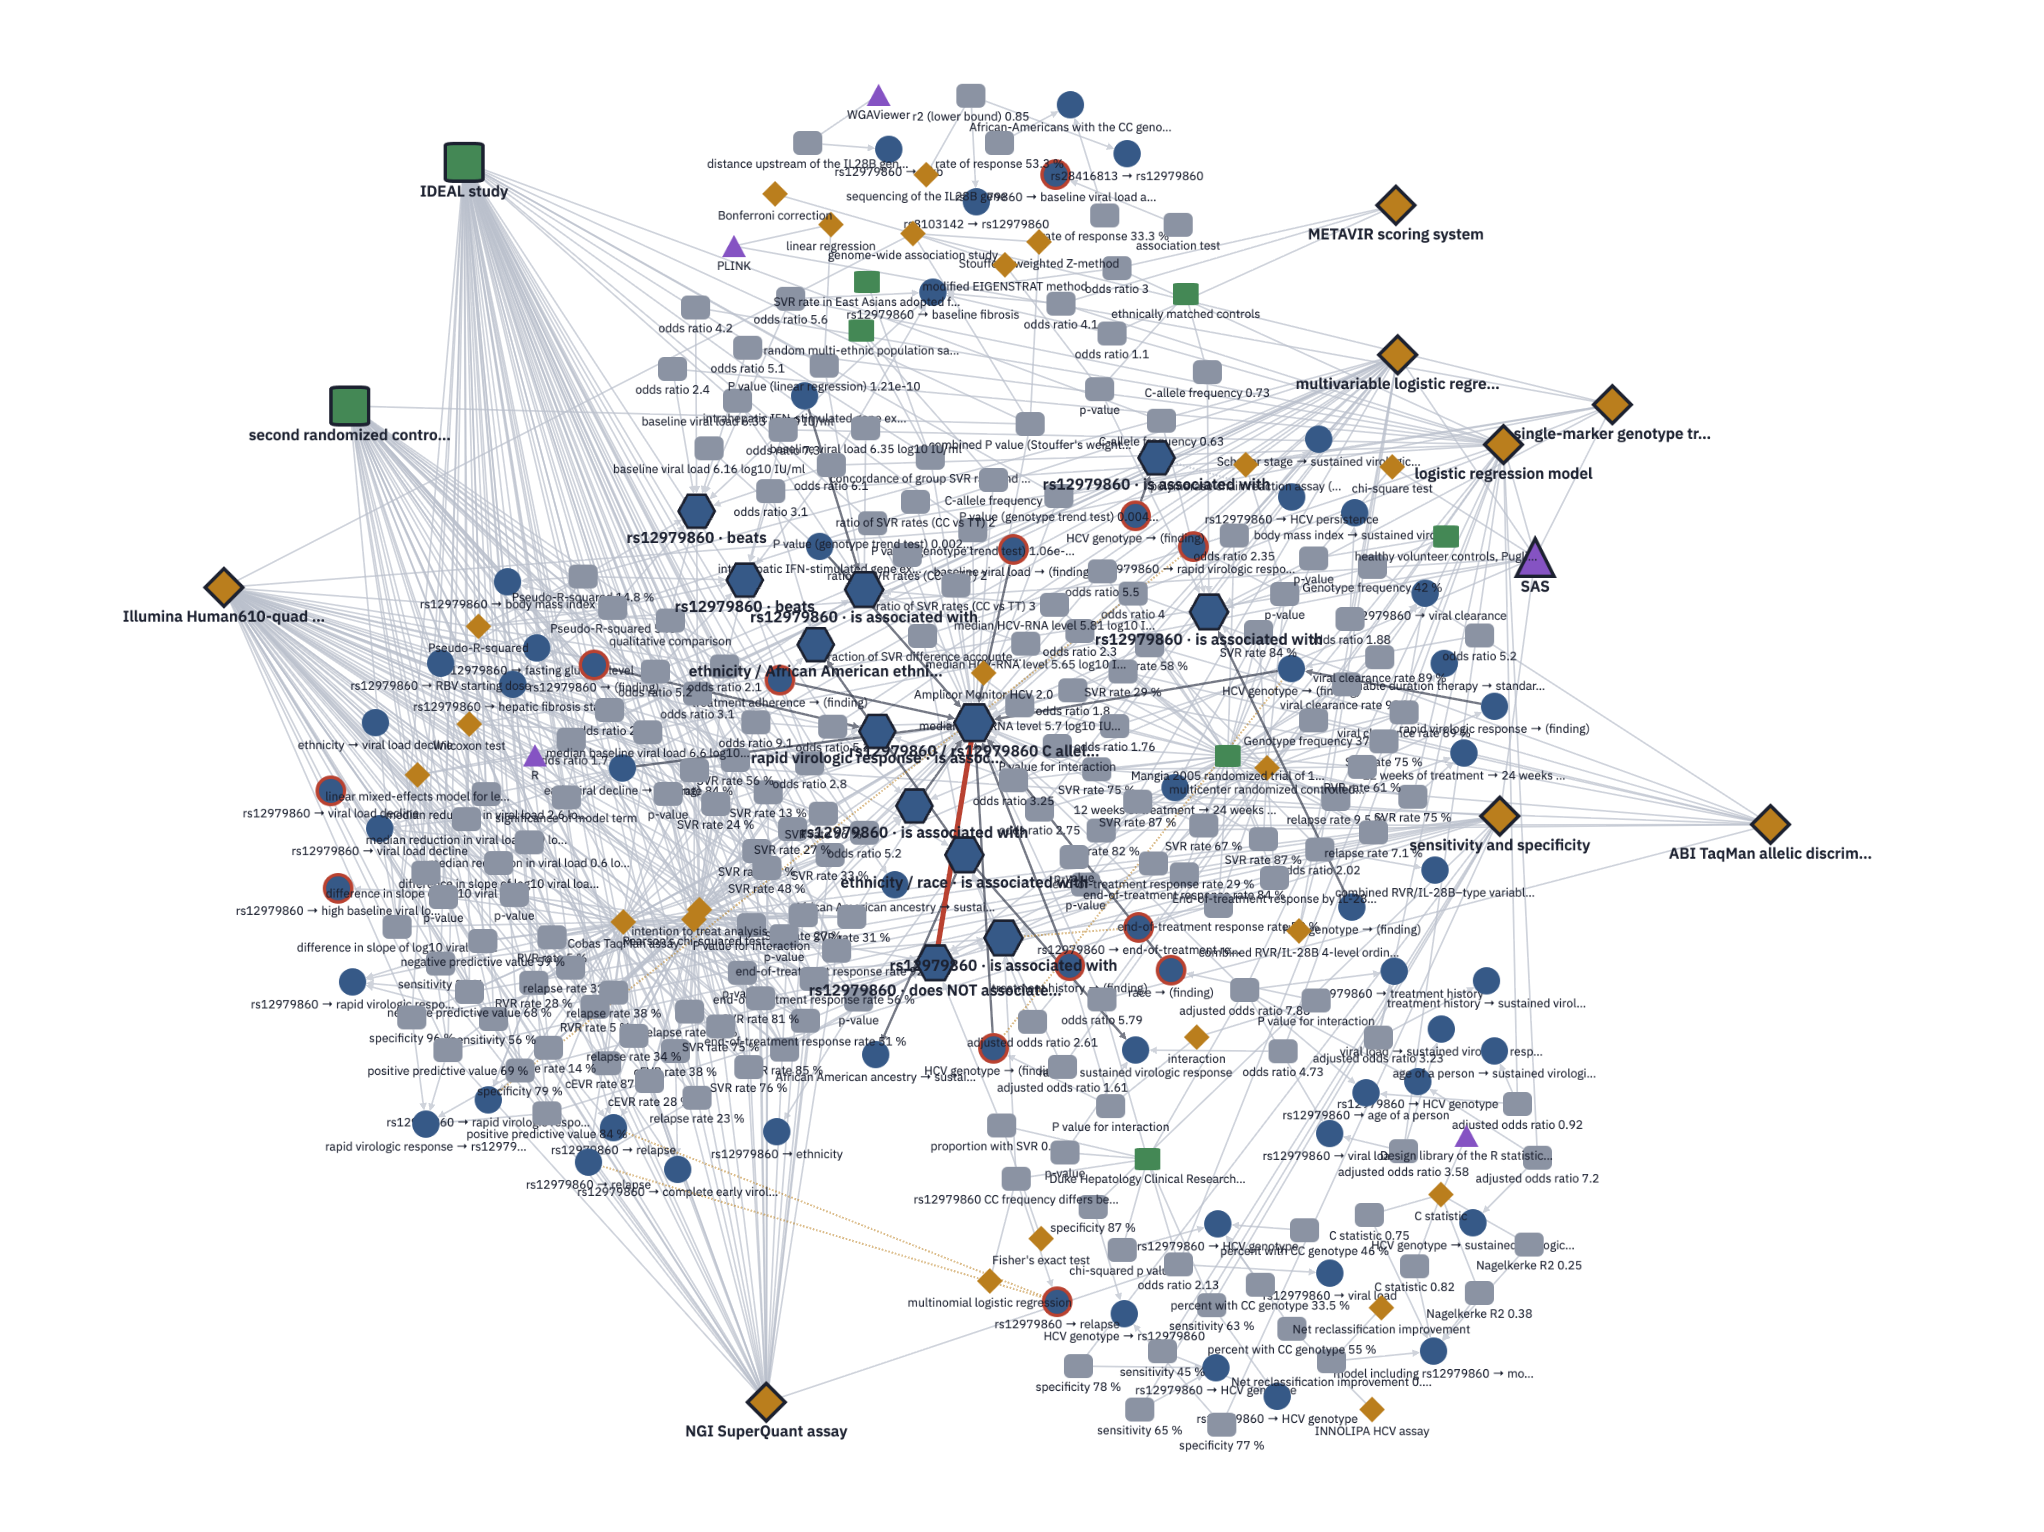
the graph consists of typed nodes and edges between them. nodes include claims, evidence, methods, materials, code, datasets. representing research this way, one thing becomes obvious: methods, code packages and other shared resources are the real generators of progress. making them visible as first-class contributions makes them legible to institutions that can then reorganize their incentive mechanisms to take such contributions more explicitly into account.
claims are represented as relationships between two entities and are thus often nexuses of cross-team collaboration: is s12979860 (a single-nucleotide polymorphism) is associated with more spontaneous clearance of hepatitis c? this also means that multiple groups do, can and should add evidence to the same claim, debating, contesting or replicating its veracity. this makes contested points in the research visible and again, allows incentives to be built around resolving them.
this medium is not meant to replace papers entirely but to supplement the scientific record with a more comprehensive and faster-growing body of knowledge and insight. papers can still be written up once everything is done, and that’s great. but papers will never include all the important contributions to science that this graph captures, like code, specific tools, negative results.
the graph is also incredible easy for llms to traverse and retrieve, allowing researchers to verifiably fetch all claims about entity x, or all datasets that have been analyzed with method y.
this is the schema for gro. note this is still evolving in order to be maximally helpful to scientists.
Claim
id: rel:2026-03-11-tw-jfh1-replicon#cl1
kind: claim
subject:   {id: wd:Q18039731, label: IL28B}
predicate: {label: predicts}
object:    {id: wd:Q7111590, label: sustained virological response}
qualifiers:
  population:   [{label: patients with chronic HCV genotype 1}]
  system:       []                                  # experimental system node ids
  intervention: [{label: peginterferon alfa-2b plus ribavirin}]
  adjusted_for: [{label: baseline viral load}]
  contrast: CC vs TT
  direction: increase
  timepoint: week 72
  other: null
negated: false
hedged: false
basis: own_result          # own_result | from_other_work | interpretation
framed_as: extension       # replication | contradiction | extension
origin:
  release: rel:2026-03-11-tw-jfh1-replicon
  by: [orcid:0000-0002-1825-0097]
grounding: {release: rel:…, artifact: runs/2026-03-09/titration.csv, locator: "row 14"}
also_stated_in:
  - release: doi:10.1002/hep.23192
    quote: "…"
    locator: "Results, para 3"
    basis: own_result
Evidence
Experimental results and analyzed data are captured preserving the relevant context to interpret the result. This includes uncertainty bands and links to related contribution types such as claims it relates to or informs, the method(s) that produced it, and the dataset it emerges from.
id: doi:10.1038/nature08309#ev3
kind: evidence
description: odds of SVR for CC versus TT genotype
measure: odds ratio
value: 7.3
value_range: null          # {low, high} when the reported value is itself a range
unit: null
ci: {low: 5.1, high: 10.4, level: 0.95}    # level null when it is not stated
error: {type: se, value: 0.18}             # sd | se | iqr | range | other
p: "<0.0001"                               # as stated
test: logistic regression
n: 1137
population: {label: patients with chronic HCV genotype 1}
outcome: sustained virological response
reference_level: TT genotype
origin: {release: doi:10.1038/nature08309, by: [person:d-ge]}
grounding: {release: …, quote: "…", locator: "Table 2"}
A negative or null result is an evidence node like any other, published the same way. Nothing in the schema makes a result that did not work harder to publish than one that did.
Method
id: rel:2026-03-11-tw-jfh1-replicon#me1
kind: method
label: JFH-1 subgenomic replicon assay
status: new                # grounded | new | composite | from_other_work | unattributed
from_other_work: null      # {as_stated: "Lohmann 1999", release: doi:… } when status says so
used_in: [rel:2026-03-11-tw-jfh1-replicon, doi:10.1002/hep.23192]
origin: {release: rel:…, by: [orcid:0000-0002-1825-0097]}
grounding: {…}
Experimental system
The material a result is obtained in, as its own node, so that reuse shows up as one shared node rather than a repeated string. This is the node that makes “nine groups built on our construct” answerable.
id: rel:2026-03-11-tw-jfh1-replicon#sy1
kind: system
label: pJFH1
system_kind: construct     # cell_line | primary_cells | replicon | construct |
                           # pseudoparticle | animal_model | other
identifiers:
  - {scheme: genbank, value: AB047640}
produced:
  by: [orcid:0000-0002-1825-0097]
  here: produced_here      # produced_here | reused | not_stated
  from_other_work: null
new: true
origin: {release: rel:…, by: [orcid:0000-0002-1825-0097]}
used_in: [rel:…, doi:10.1038/nm1268]
grounding: {…}
identifiers takes the schemes genbank, rrid, atcc, addgene, doi, url and other. Systems derived from other systems are linked by derived_from, which records the modification.
Data
id: doi:10.1038/nature08309#da1
kind: data
label: IDEAL study
identifiers:
  - {scheme: nct, value: NCT00081770}
produced:
  context: >-
    phase 3 RCT of peginterferon alfa-2b vs alfa-2a with ribavirin,
    genotype 1, US sites
  by: [person:j-mchutchison]
  from_other_work: {as_stated: "McHutchison 2009"}
  here: reused             # produced_here | reused | not_stated
status: public_registered
access: not_stated
origin: {release: doi:10.1038/nature08309, by: [person:d-ge]}
used_in: [doi:10.1038/nature08309]
grounding: {…}
identifiers records every identifier published for the dataset, each with a scheme: nct, doi, zenodo, dbgap, geo, sra, genbank, pdb, dbsnp, ega, url, other. An empty list means none was given.
produced.context is the study or setting the data came from — trial, cohort, lab system, collection period, site. produced.by is who made it. origin stays what it is for every node: the release that first brought the data into the graph, which for reused data is rarely the producer.
Code
id: rel:2026-04-02-tw-svr-model#co1
kind: code
label: hcv-svr-glm
code_kind: project_code    # package | project_code
status: released           # released | stated_not_released
url: https://github.com/…
version: v1.2.0
produced: {by: [person:…], here: produced_here}
origin: {…}
grounding: {…}
Person
A person is a node so that credit is a link rather than a repeated string, and so that the same person publishing twice is one node. This is what makes the graph answerable in the direction that matters to the people in it: what have I put into the world, and what has been built on it.
id: orcid:0000-0002-1825-0097
kind: person
name: "Takaji Wakita"
also_published_as: ["T. Wakita"]
ids:
  - {scheme: orcid,     value: "0000-0002-1825-0097"}
  - {scheme: gscholar,  value: "xxxxxxxxxxxx"}
  - {scheme: ror,       value: "https://ror.org/…"}     # affiliation handle
first_seen_in: rel:2026-03-11-tw-jfh1-replicon
ids is a list because one person is reachable through several handles, and because the handle one release carries is not always the one you want to join on. Schemes in use: orcid, gscholar, ror, isni, wikidata, email, url, other. The list may be empty — a person named with no identifier anywhere is still a person node, with a corpus-local person:<slug> id.
Credit lands in three places, which answer different questions:
byon the release — who published this, and who is corresponding.origin.byon a node — who is credited with introducing it.produced.byon data, systems and code — who made the material, which is often not the person who introduced it to the graph.
An authored_by edge runs from any node to the people credited for it, so the same question can be asked of the graph without walking releases.
Edges
| type | from → to |
|---|---|
supports, contradicts | evidence → claim (optional jointly_with: [evidence ids]) |
produced_by | evidence → method |
uses_data | evidence → data |
uses_code | evidence or method → code |
uses_system | evidence or method → system |
composed_of | method → method (records the modification) |
derived_from | system → system (records the modification) |
authored_by | any node → person |
| matcher relations | claim → claim; matcher runs only |
Every edge carries from_kind and to_kind, so a consumer never has to look its endpoints up, and either stated_in or made_by.
Claim relations derived from the fields
For two claims from different releases, these follow from the fields alone and are not stored:
- exact match — same subject, predicate, object,
negatedand qualifiers. They are one node. - refines — same subject, predicate, object and
negated; one claim’s qualifiers are a strict superset of the other’s. - conflicts — same subject, predicate and object, opposite
negated, and one claim’s qualifiers contain the other’s. - same relation, other scope — same subject, predicate, object and
negated; the qualifiers differ and neither set contains the other. - same relation, inverse outcome — one claim’s object is the vocabulary inverse of the other’s (direction flipped, contrast dropped), with subject, predicate and
negatedagreeing.
Anything else that looks alike is for a matcher, which emits the same relation vocabulary — same_claim, refines, same_relation_other_scope, conflicts, agrees — as a made_by edge. The division is that the field rules fire when subject, predicate and object all match and only the qualifiers are in question; a matcher fires when the entities match but the predicates differ, and has to read them to type the relation. The predicate is a matching input, not a matching key: with an open predicate vocabulary, most predicates are used once, and keying on them would stop the field rules from ever firing across releases.
What this draft leaves out
- Versioning and concurrency, which publishing-as-you-go needs and this draft does not have. A claim published early and revised later, several people adding to one release at once, what merges and what conflicts, and what a reason-for-change is attached to — all open. The schema below is written as though nodes are published once.
- References and citations. The working version captures every reference-list entry and every citing passage, and resolves them into node-level edges in a later pass. That layer reconstructs a graph from finished papers; a release that credits earlier work does it inline, through
from_other_work. The reconstruction layer is omitted here rather than trimmed. - Vocabulary resolution. The passes that resolve entity labels and predicates to shared vocabulary, and the vocabulary table itself.
- Everything operational: extraction, build and matcher tooling, review workflow, and the publishing endpoint that would mint release keys and stamp
published_at.****